
Key Driver Analysis
Our Probabilistic Structural Equation Model is now complete, and we can use it to perform the analysis part of this exercise, namely to find out what “drives” . We return to the Validation Mode .
To understand the relationship between the factors and , we want to “tune out” all Manifest variables for now. We can do so by right-clicking the Classes icon in the bottom right corner of the Graph Panel window. This brings up a list of all Classes. By default, all are checked and thus visible.
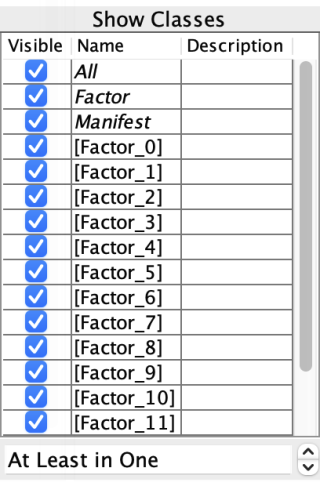
For our purposes, we want to un-check All and then only check the class Factor.
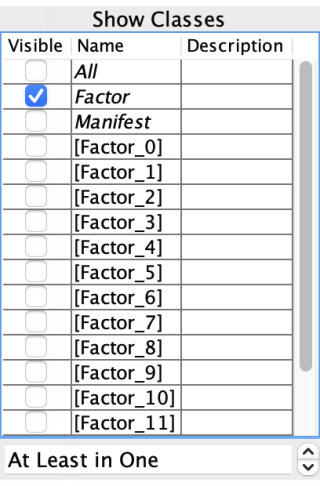
In the resulting view, all the Manifest Nodes are transparent, so the relationship between the Factors becomes visually more prominent. By de-selecting the Manifest Nodes in this way, we also exclude them from the following visual analysis.
Target Analysis
In line with our objective of learning about the key drivers in this domain, we proceed to analyze the association of the newly created Factors with .
We return to the Validation Mode , in which we can use two approaches to learn about the relationships between Factors and the Target Node: we first perform a visual analysis and then generate a report in table format.
Visual Analysis
We initiate the visual analysis by selecting Menus > Analysis > Visual > Target > Target’s Posterior > Curves > Total Effects:
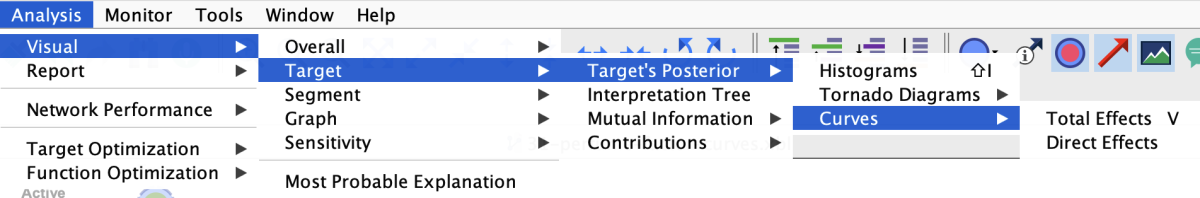
This brings up a dialog box with the options shown below. Given the context, selecting Mean for both the Target Node and the Nodes is appropriate.
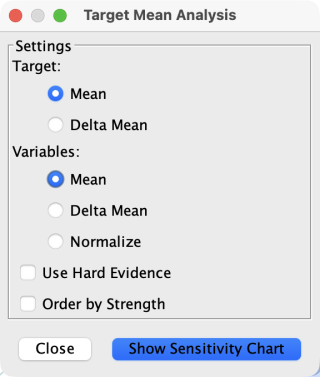
Choose Mean for both Target and Variables, leaving Use Hard Evidence and Order by Strength unchecked. Upon clicking Show Sensitivity Chart, the resulting plot shows the response curves of the Target Node as a function of the values of the Factors. This allows an immediate interpretation of the strength of the associations.
Target Analysis Report
As an alternative to the visual analysis, we now run the Target Analysis Report: Menus > Analysis > Report > Target > Total Effects on Target.
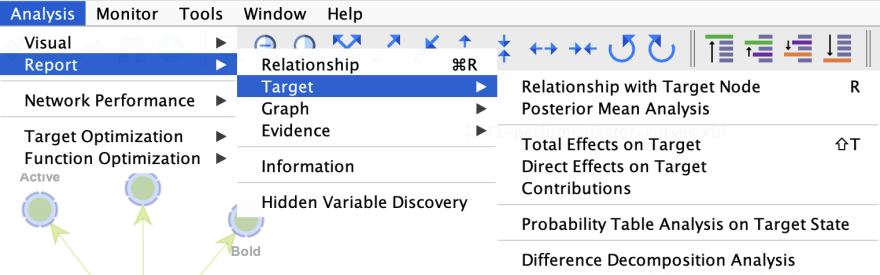
Although “effect” carries a causal connotation, we must emphasize that we strictly examine associations. This means that we perform observational inference as we generate this report.
In the Effect Analysis dialog, clear Compute Credible Intervals and click OK to reproduce this point-estimate comparison. A new window presents the report. Under Menus > Window > Preferences > Reporting, enable Show Node Long Names to display the Factors’ representative Manifest names. Show Node Comments is a separate setting.
The Total Effect (TE) is the change in the mean of the Target Node associated with, and not necessarily caused by, a small change in the mean of the driver node under study. BayesiaLab estimates it as the derivative of the Target Node with respect to the driver node.
where is the analyzed variable and is the Target Node.
This way of measuring the effect of the Factors on the Target Node assumes the relationships to be locally linear. Even though this is not always a correct assumption, it can be reasonable to simulate small changes in satisfaction levels.
As per the report, provides the strongest Total Effect with a value of 0.3982. This means that observing an increase of one unit in the level of the concept represented by predicts a posterior probability distribution of that has an expected value that is 0.3982 higher compared to the marginal value.
The Standardized Total Effect (STE) is also displayed. It represents the Total Effect multiplied by the ratio of the standard deviation of the driver node and the standard deviation of the Target Node.
This means that Standardized Total Effect takes into account the “potential” of the driver under study.
In the report, the results are sorted by the absolute size of the Standardized Total Effect in descending order. This immediately highlights the order of importance of the Factors relative to the Target Node, .
Independence Tests
In the columns further to the right in the report, the results of independence tests between the nodes are reported:
- Chi-Square () test or G-test: The independence test is computed on the basis of the network between each driver node and the target variable. It is possible to change the type of independence from the Chi-Square () test to the G-test via
Menus > Window > Preferences > Tools > Statistical Tools. - Degree of Freedom: Indicates the degree of freedom between each driver node and the Target Node in the network.
- p-value: the p-value is the probability of observing a value as extreme as the test statistic by chance.
If a dataset is associated with the network, as is the case here, the independence test, the degrees of freedom, and the p-value are also computed directly from the underlying data.
Factors versus Manifest Nodes
For overall interpretation purposes, looking at Factor-level drivers can be illuminating. Often, it provides a useful big-picture view of the domain. However, we need to consider the Manifest-level drivers to identify specific product actions. As pointed out earlier, the Factor-level drivers only exist as theoretical constructs, which cannot be directly observed in data. As a result, changing the Factor nodes requires manipulating the underlying Manifest nodes. For this reason, we now switch back our view of the network in order to only consider the Manifest nodes in the analysis. We do that by right-clicking the Classes icon in the bottom right corner of the Graph Panel window. This brings up the list of all Classes, of which we only check the Class Manifest. Now, all Factors are translucent and excluded from the analysis.
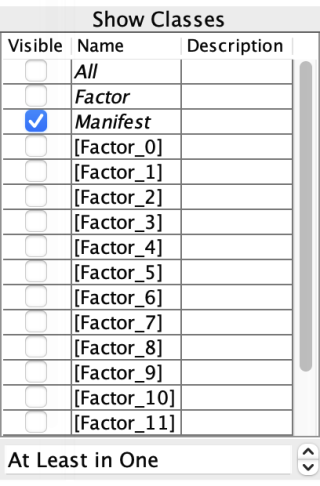
We repeat both the Target Mean Analysis and the Total Effects on Target report.
Not surprisingly, the Manifest Nodes show a similar pattern of association as the Factors. However, there is one important exception: the Manifest Node shows a nonlinear relationship with . Identify the nonlinear curve by its label in the legend. Note that by hovering over a curve or a node name, BayesiaLab highlights the corresponding item in the legend or the plot.
Also, we can see that was recorded on a 1−5 scale rather than the 1−10 scale that applies to the other nodes. is a so-called “JAR” variable, i.e., a variable that has a “just-about-right” value. In the context of perfumes, this characteristic is obvious. A fragrance that is either too strong or too light is undesirable. Instead, there is a value somewhere in between that would make a fragrance most attractive. The JAR characteristic is prototypical for variables representing sensory dimensions, e.g., saltiness or sweetness.
This emphasizes the importance of visual analysis, as the nonlinearity goes unnoticed in the Total Effects on Target report. In the current report, ranks 45th of the 47 Manifest variables by the absolute size of Standardized Total Effect.
It turns out to be rather difficult to optimize a JAR-type variable at a population level. For example, increasing would reduce the number of consumers who find the fragrance too subtle. On the other hand, an increase in would presumably dismay some consumers who believed the original level to be appropriate.
Constraints via Costs
As this driver analysis model is intended for product optimization, we need to consider any possible real-world constraints that may limit our ability to optimize any of the drivers in this domain. For instance, a perfumer may know how to change the intensity of a perfume but may not know how to directly affect the perception of “pleasure.” In the original study, a number of such constraints were given.
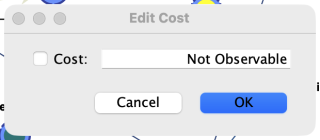
In BayesiaLab, we can conveniently encode constraints via Costs, which is a Node Property. More specifically, we can declare any node as Not Observable, which in this context means that they cannot be considered with regard to optimization. Costs can be set by right-clicking on an individual node and then selecting Properties > Cost.
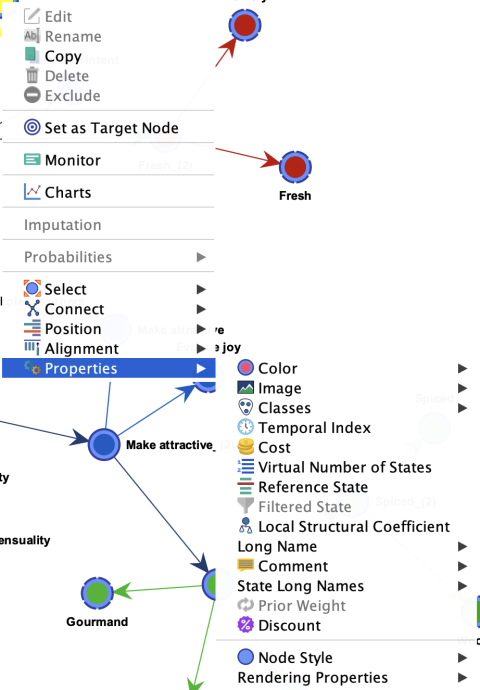
This brings up the Edit Cost dialog for an individual node. By default, all nodes have a cost of 1.
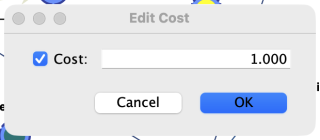
Unchecking the box Cost or setting a value ≤0 results in the node becoming Not Observable.
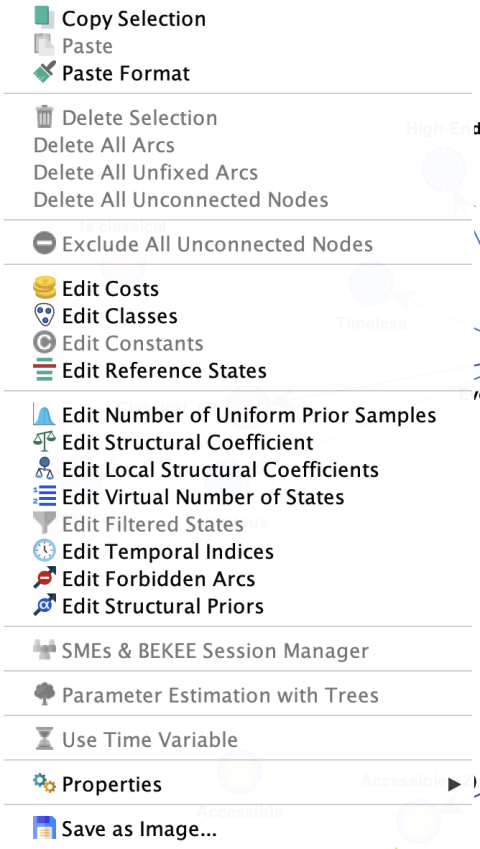
Alternatively, we can bring up the Cost Editor for all nodes by right-clicking on the Graph Panel and then selecting Edit Costs from the Contextual Menu.
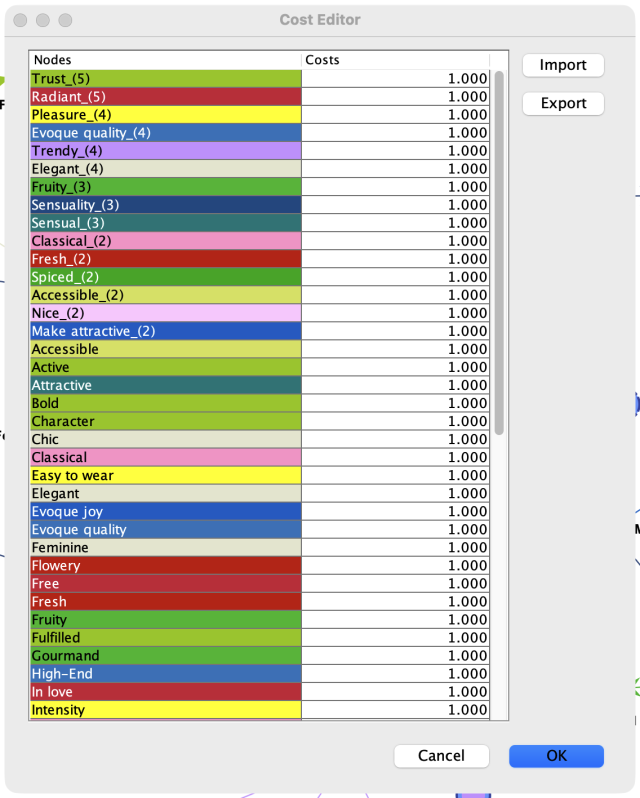
The Cost Editor presents the default values for all nodes.
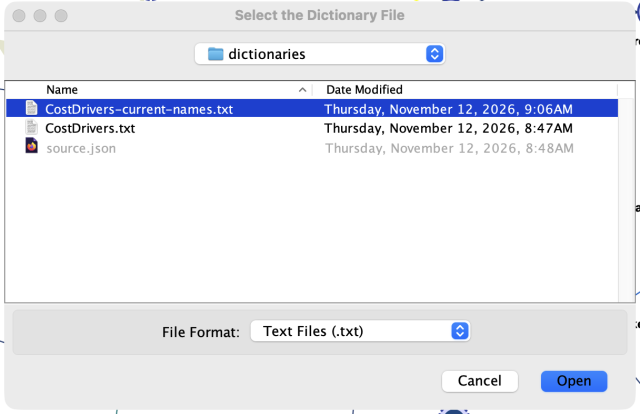
Again, setting values to zero will make nodes Not Observable. Instead of applying this setting node by node, we can import a Cost Dictionary that defines the values for each node. A selectable excerpt from the verified working dictionary is shown below. Not Observable is represented by 0. The original dictionary is preserved; its historical names Greedy, Wooded, Trend, and Corresponds have been mapped to Gourmand, Woody, Trendy, and Suits me. Factor identifiers retain their brackets.
Product=0
Purchase\ Intent=1.0
Fresh=1.0
Flowery=1.0
Gourmand=1.0
Spiced=1.0
Woody=1.0
Sweet=1.0
Easy\ to\ wear=0
Rich=0
Fruity=1.0
Modern=0
Original=1.0
Feminine=1.0
Elegant=0
Tenacious=1.0
Evoque\ quality=0
Evoque\ joy=0
Make\ attractive=0
Universal=0
Trendy=0
Personality=1.0
From within the Cost Editor, we can use the Import button to associate a Cost Dictionary. Alternatively, we can select Menus > Data > Associate Dictionary > Node > Costs.
Upon import, the Cost Editor reflects the new values, and the presence of non-default values for costs is indicated by the Cost icon in the lower right-hand corner of the Graph Panel.
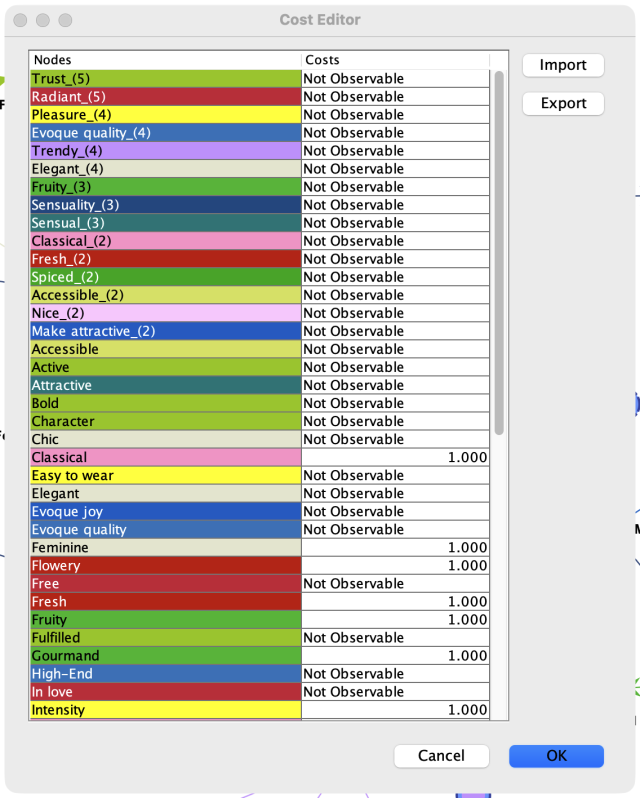
The network retains its class colors. Use the explicit Not Observable statuses in the Cost Editor to identify constrained nodes; the network below shows their structural context.
It is important to note that all Factors are also set to Not Observable in our example. In fact, we do have two options here:
- The optimization can be done at the first level of the hierarchical model, i.e., using the Manifest variables;
- The optimization can be performed at the second level of the model, i.e., using the Factors.
Most importantly, these two approaches cannot be combined as setting evidence on Factors will block information coming from Manifest variables. Formally declaring the Factors as Not Observable tells BayesiaLab to proceed with option #1. Indeed, we plan to perform optimization using the Manifest variables only.
Multi-Quadrant Analysis
The network we have analyzed thus far modeled as a function of perceived perfume characteristics. It is important to point out that this model represents the entire domain of all 11 tested perfumes. However, it is reasonable to speculate that different perfumes have different drivers of . Furthermore, for purposes of product optimization, we certainly need to look at the dynamics of each product individually.
BayesiaLab assists us in this task by means of Multi-Quadrant Analysis. This function can generate new networks as a function of a Breakout Node in an existing network. This is where the node comes into play. It was excluded during the preceding analysis. In the current version, include Product in a separate working copy before opening Multi-Quadrant; excluded nodes do not appear in the Breakout Variable list. Verify Product’s probability table against the survey counts and save the working copy. Our objective is to generate a set of networks that model the drivers of for each perfume individually, as identified by the breakout variable.
We start the Multi-Quadrant Analysis by selecting Menus > Analysis > Visual > Segment > Multi-Quadrant.
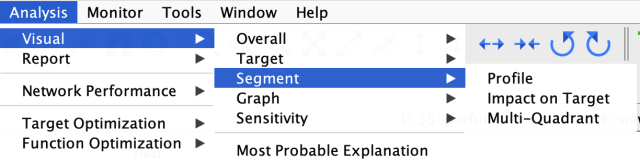
This brings up the dialog box, in which we need to set a number of options:
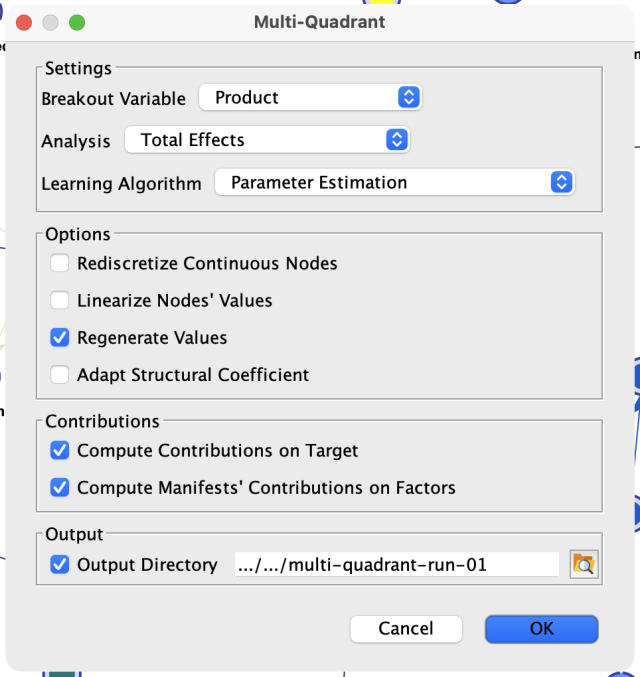
Firstly, the Breakout Variable must be set to to indicate that we want to generate a network for each state of . For Analysis, we have several options: We choose Total Effects to be consistent with the earlier analysis. Regarding the Learning Algorithm, we select Parameter Estimation. This choice becomes evident once the dataset representing the “overall market” is split into 11 product-specific subsets. The subsets contain 119–121 records: Product 7 has 119, Products 11 and 12 have 121 each, and the other eight products have 120 each. Given that most of our variables have 5 states, learning a structure with a dataset that small would be challenging.
This also explains why we used the entire dataset to learn the PSEM structure, which all the products will share. However, using Parameter Estimation will ensure that the parameters, i.e., the probability tables of each network, will be estimated based on the subsets of records associated with each state of .
Among the Options, we check Regenerate Values. This recomputes, for each new network, the values associated with each state of the discretized nodes based on the respective subset of data.
There is no need to check Rediscretize Continuous Nodes because all discretized nodes share the same variation domain, and we required equal distance binning during the data import. However, we do recommend using this option if the variation domains are different between subsets in a study, e.g., sales volume in California versus Vermont. Without using the Rediscretize Continuous Nodes option, it could happen that all data points for sales in Vermont end up in the first bin, effectively transforming the variable into a constant.
Furthermore, we do not check the option for Linearize Nodes’ Values either. This function reorders a node’s states so that its states’ values have a monotonically positive relationship with the values of the Target Node. Applying this transformation to the node would artificially increase its impact. It would incorrectly imply that it is possible to change a perfume in a way that simultaneously satisfies consumers who rated it too subtle and those who rated it too strong. Needless to say, this is impossible.
Finally, enable both Compute Contributions on Target and Compute Manifests' Contributions on Factors to support interpretation of each product-specific network. Leave Adapt Structural Coefficient off for this parameter-estimation run.
Upon clicking OK, 11 networks are created and saved to the Output Directory defined in the dialog box. Each network is then analyzed with the specified Analysis method to produce the Multi-Quadrant Plot.
The x-value of each point indicates the mean value of the corresponding Manifest Node, as rated by those respondents who have evaluated Product 1; the position on the y-axis reflects the computed Total Effect.
From the contextual menu, we can choose Show Horizontal Scales and Show Vertical Scales, which provide the range of positions of the other products.
Using Horizontal Scales provides a quick overview of how the product under study is rated vis-à-vis other products. The Vertical Scales compare the importance of each dimension with respect to . Select the individual product using its box in the legend on the right; select Product 1 for the following examples.
Drawing a rectangle with the cursor zooms in on the specified area of the plot.
The meaning of the Horizontal Scales and Vertical Scales becomes apparent when hovering over any dot, as this brings up the position of the other (competitive) products with regard to the currently highlighted attribute.
This means, for instance, that Product 2 and Product 8 are rated lowest and highest, respectively, on the x-scale with regard to the variable . Regarding the Total Effect on , Product 12 and Product 10 mark the bottom and top end, respectively (y-scale).
From a product management perspective, this suggests that for Product 1, with regard to the attribute , there is a large gap to the level of the best product, i.e., Product 8 (just above Product 7). So, one could interpret the variation from the status quo to the best level as “room for improvement” for Product 1.
On the other hand, as we can see below, the variables , , and have a greater Total Effect on . Original is slightly below Fresh in this run. These relative positions will soon become relevant as we must simultaneously consider the potential for improvement and the importance of optimizing .
BayesiaLab’s Export Mean Value Ranges function allows us to save the variation domain for each driver, i.e., the minimum and maximum mean values observed across all products in the study.
Knowing these variations will be useful for generating realistic scenarios for subsequent optimization. However, what do we mean by “realistic”? Ultimately, only a subject matter expert can judge how realistic a scenario is. However, a good heuristic is whether or not a certain level is achieved by any product in the market. One could argue that the existence of a certain satisfaction level for some product means that such a level is not impossible to achieve and is, therefore, “realistic.”
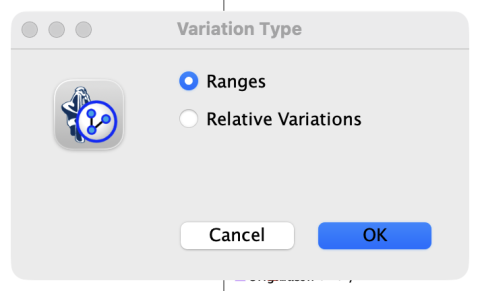
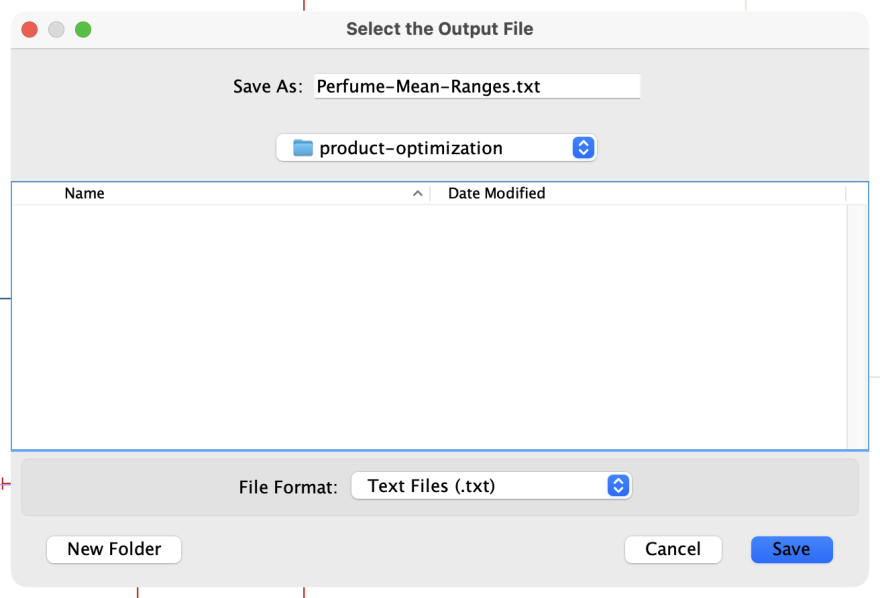
Click Export Mean Value Ranges, select Ranges in the Variation Type dialog, and save the lower and upper mean-value bounds to a text file for subsequent use in optimization. Here we use Perfume-Mean-Ranges.txt; the selectable excerpt below preserves all thirteen native ranges.
Fresh=6.208333333333334 6.866666666666667
Flowery=6.583333333333332 7.305785123966944
Gourmand=5.616666666666667 6.516666666666667
Spiced=4.216666666666668 5.041666666666667
Woody=4.616666666666667 5.241666666666666
Sweet=5.408333333333333 6.608333333333334
Fruity=6.008333333333334 7.083333333333334
Original=5.466666666666668 6.466666666666667
Feminine=6.800000000000001 7.841666666666667
Tenacious=5.591666666666668 6.851239669421487
Personality=5.650000000000001 6.783333333333333
Classical=5.700000000000001 6.441666666666666
Intensity=2.7750000000000004 3.3